Headless mode and screenshots
Render JavaScript before mirroring a page or capture full-page PNG files only.
Render before mirroring
site-scraper https://www.example.com --headlessAdd --screenshot to save a full-page PNG for every page discovered during that headless crawl:
site-scraper https://www.example.com --headless --screenshotScreenshots without a crawl
The screenshot subcommand captures one URL and does not mirror HTML or assets:
site-scraper screenshot https://www.example.comFor a batch, provide a UTF-8 text file with one URL per line. Blank lines and lines beginning with
# are ignored.
# public pages
https://www.example.com/
https://www.example.com/about/
site-scraper screenshot --file urls.txt --output shots/ --concurrency 2A real capture
This is casoon.dev as the screenshot subcommand saved it on 26 October 2026, with the default desktop viewport. The run took 9 seconds and wrote a PNG of 1440 × 5348 pixels; the image below is scaled to 960 pixels wide and converted to WebP for this page.
site-scraper screenshot https://casoon.dev/
# screenshots/casoon.dev--index.png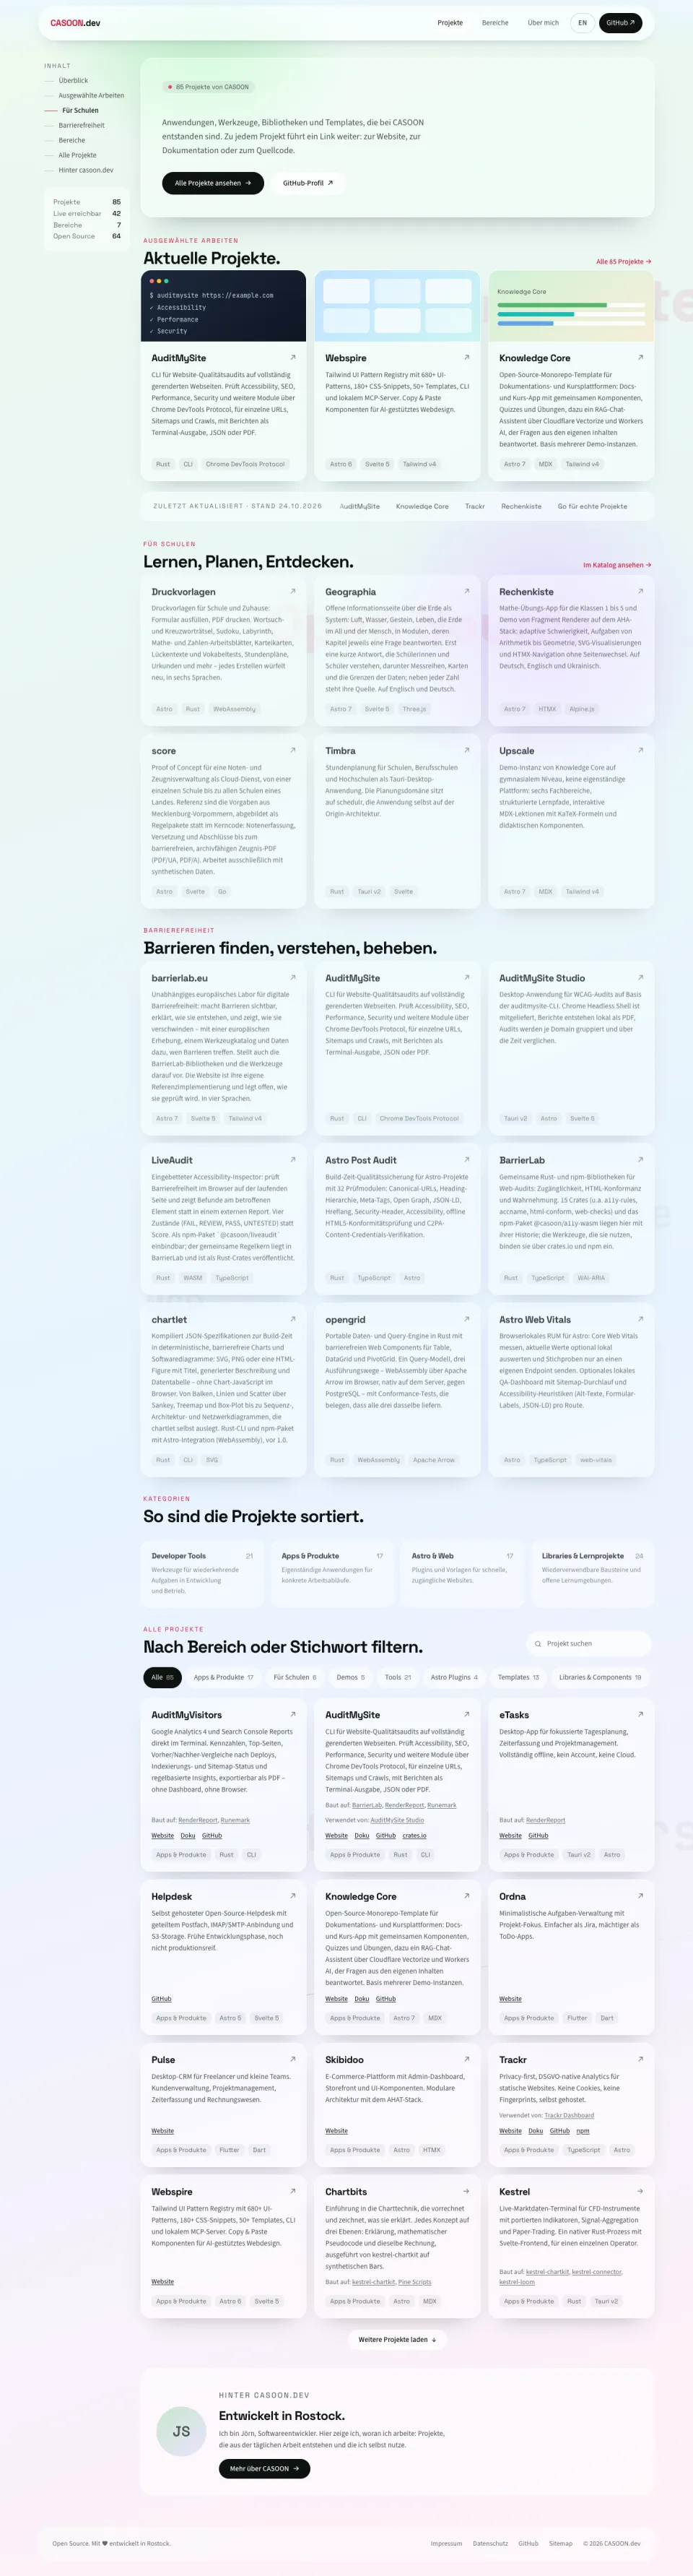
Use --device tablet or --device mobile for the other viewports; the
CLI reference lists their sizes.
Every URL is validated before Chrome starts. Files use readable, deterministic names such as
example.com--index.png and example.com--search--q-astro.png; colliding names receive a stable
short hash. Existing unrelated screenshots in the output directory are kept.
Caution
The screenshot subcommand and headless crawling require a build with the headless feature and
a local Chrome or Chromium installation.